Arabic Text Classification
An Arabic NLP project that applies preprocessing and supervised machine-learning workflows to analyze and classify Arabic text.
Problem
Arabic text needs language-aware preprocessing before standard machine-learning models can extract useful signals for classification.
My Role
Prepared the data-processing workflow, built classification experiments, compared models and presented the project training process.
Tools
- Python
- pandas
- PyArabic
- scikit-learn
- TF-IDF
- Naive Bayes
- Linear SVM
- Logistic Regression
- Matplotlib
Dataset / Inputs
Arabic text samples processed through normalization, cleaning, feature extraction and supervised train / test evaluation workflows.
Results
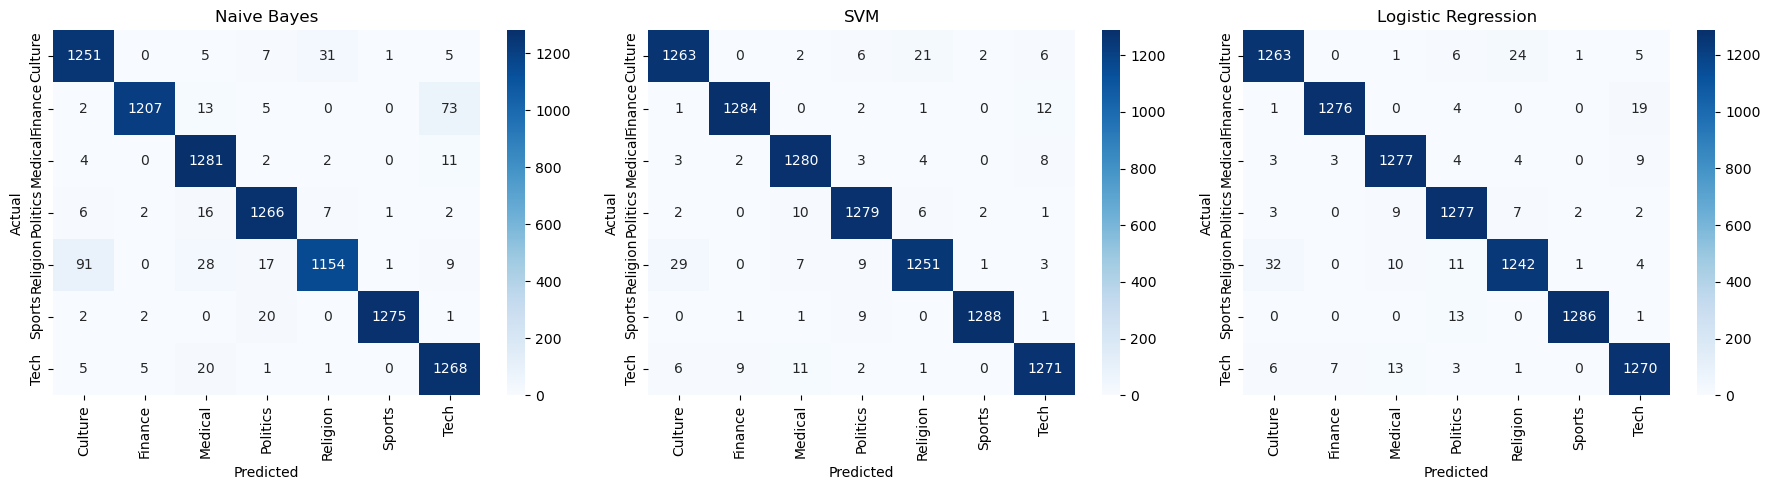
The project notebook compared multiple models and recorded strong results, including SVM accuracy around 0.9798 in the embedded comparison output.
Challenges
Managing Arabic normalization choices, choosing meaningful text features and comparing models fairly across accuracy and training time.
Demo & Screenshots
GitHub
Repository status: Private / available upon request. The public GitHub profile is linked below. For a walkthrough, code discussion, screenshots or a demo, contact me directly on WhatsApp.